April 1 through June 30 2026
Overview
Six selected cases show how AI integrations, coding tools, and browser agents can turn ordinary inputs or delegated access into security exposure. Defenders should constrain tool execution and credentials, preserve input provenance, and monitor the actions agents take.
Coverage includes incidents and technical disclosures published during the quarter. Disclosure dates and occurrence dates are distinguished. Two entries concern observed malicious activity; four concern research demonstrations or controlled validation. The selection is not exhaustive and does not imply six independent criminal attacks.
Cases covered
Comment and Control: Research disclosure
Context ai compromise and Vercel account pivot: Confirmed incident
Semantic Kernel prompt to host code execution: Research disclosure
Sentry Agentjacking: Controlled validation
Langflow cross tenant flow execution and RCE attempts: Observed exploitation activity
BioShocking browser agent context manipulation: Research disclosure
Cross case findings
- Untrusted content entered through collaboration text, telemetry, and web pages, then influenced privileged actions.
- Delegated identities and accessible secrets determined how far an attacker could reach.
- Conventional authorization and code-execution flaws remained central in AI platforms.
- Controls should validate each action outside the model and record the identity, tool, input source, and destination.
Mapping and evidence conventions
Mappings below are analyst interpretations using the OWASP Top 10 for LLM Applications 2026 and Top 10 for Agentic Applications 2026. The LLM edition was published after this reporting quarter; mappings are retrospective. Category numbers follow the published 2026 PDF. A conventional infrastructure breach is not automatically an LLM or agentic exploit.
Incident facts are attributed to the primary references listed at the end. Financial loss is included only where established; none of these selected sources quantifies it. Later source updates are used to clarify evidence, not to expand the quarter’s incident count. This summary does not imply OWASP endorsement.
Comment and Control
Description
Attacker-controlled GitHub text redirected three coding agents into exposing runtime secrets through GitHub comments or commits. The research showed how routine collaboration data can become an instruction channel.
Incident Summary
Incident Name: Comment and Control
Date and Location: Public disclosure April 15, 2026; underlying reports began in 2025. Online GitHub workflows; no victim geography established.
Affected Organizations: Anthropic Claude Code Security Review, Google Gemini CLI Action, and GitHub Copilot Agent deployments with relevant permissions.
Attack Type: Research demonstration; indirect prompt injection and credential exfiltration.
System Impacted: AI coding workflows and their execution environments.
Impact Assessment
Demonstrated token and API-key disclosure could enable repository access, account abuse, or downstream compromise. Exposure depended on workflow permissions and available secrets. The disclosure did not establish measured criminal losses.
Attack Breakdown
A PR title, issue comment, or hidden HTML comment carried malicious instructions. An agent processing that text used its execution permissions to obtain secrets and publish them back through GitHub. Some workflows could trigger automatically; the Copilot path required issue assignment.
OWASP Top 10 LLM Risks Exploited
- LLM01:2026 Prompt Injection: repository text redirected the model.
- LLM03:2026 Excessive Agency: execution and publishing privileges enabled the attack.
- LLM02:2026 Sensitive Information Disclosure: secrets appeared in attacker-accessible output.
OWASP Top 10 Agentic Security Risks Exploited
- ASI01 Agent Goal Hijack: review or triage became credential extraction.
- ASI02 Tool Misuse and Exploitation; ASI03 Identity and Privilege Abuse: legitimate commands and tokens supported leakage.
CVE References: No specific CVE identifier is provided in the researcher disclosure. Treat the three variants as one related exploit family.
Potential Mitigations
Technical defenses: Separate secret-bearing jobs from processing untrusted contributions; issue narrowly scoped tokens; restrict commands and repository writes; inspect agent output for secrets.
Policy improvements: Require security review before enabling agent workflows on external PRs or issues. Document who may grant write permissions.
User education: Teach maintainers that hidden comments and PR titles are untrusted input, even when GitHub hosts them.
Call to Action
Inventory agent-triggered GitHub workflows and identify which can read secrets or publish content. Test with harmless injected instructions, remove unnecessary execution privileges, and review prior runs for unexpected secret access or comments.
Source References: See Comment and Control in the consolidated references.
Context ai compromise and Vercel account pivot
Description
A compromise of third-party AI service Context.ai enabled takeover of a Vercel employee account and access to internal systems. Attackers subsequently accessed environment variables belonging to some customers.
Incident Summary
Incident Name: Context ai compromise and Vercel account pivot
Date and Location: Vercel disclosed the incident April 19, 2026. Exact initial compromise date is unspecified; cloud services and customer accounts, geography unspecified.
Affected Organizations: Context.ai, Vercel, and a limited subset of Vercel customers.
Attack Type: Confirmed security incident; third-party compromise and account takeover.
System Impacted: Google Workspace OAuth access, a Vercel employee account, and environment-variable storage.
Impact Assessment
Vercel reported compromised customer accounts and exposure of environment variables not marked sensitive. Accessible secrets created downstream risk and required rotation. The bulletin did not quantify financial loss or establish npm package tampering.
Attack Breakdown
The attacker pivoted from Context.ai into an employee Google Workspace account, then the employee Vercel account and an internal environment. They enumerated and decrypted environment variables classified as non-sensitive. This was an identity and integration failure; prompt injection was not established.
OWASP Top 10 LLM Risks Exploited
- No direct LLM vulnerability is established. LLM04:2026 Supply Chain is an ecosystem analogy for dependence on a third-party AI service, rather than a proven model or artifact supply-chain exploit.
OWASP Top 10 Agentic Security Risks Exploited
- No direct agentic exploit is established. ASI03 Identity and Privilege Abuse is a control analogy for delegated identity risk; the source does not establish an autonomous agent attack.
CVE References: No specific CVE identifier is listed in the Vercel incident bulletin.
Potential Mitigations
Technical defenses: Revoke suspect OAuth grants and sessions; rotate potentially exposed credentials; mark secrets as sensitive; correlate identity and environment-variable access logs.
Policy improvements: Require approval and scope review for AI-service OAuth applications, including employee-authorized services.
User education: Explain that connecting an AI tool can delegate durable access to corporate data and accounts.
Call to Action
Review AI-service OAuth grants across the organization and investigate the app indicator published by Vercel. Identify exposed secrets and rotate them at their issuing services. Trace subsequent use of those credentials across cloud, source-control, and deployment systems.
Source References: See Context ai compromise and Vercel account pivot in the consolidated references.
Semantic Kernel prompt to host code execution
Description
Microsoft demonstrated two Semantic Kernel flaws that let malicious prompts reach host execution paths. Unsafe search-filter evaluation and exposed file-transfer helpers undermined the intended boundary between agent tools and the host.
Incident Summary
Incident Name: Semantic Kernel prompt to host code execution
Date and Location: Technical disclosure May 7, 2026; fixes preceded that publication. Research environments; no affected-victim geography established.
Affected Organizations: Organizations using affected Semantic Kernel Python or .NET configurations.
Attack Type: Research demonstration; prompt injection, unsafe evaluation, and host file-write abuse.
System Impacted: In-Memory Vector Store search and SessionsPythonPlugin integrations.
Impact Assessment
Demonstrated outcomes included host code execution and arbitrary file access or writes in relevant configurations. These capabilities could expose secrets or enable persistence. The report did not document a confirmed criminal campaign or financial loss.
Attack Breakdown
One path sent model-controlled search arguments into unsafe Python filter evaluation and bypassed restrictions. Another exposed a file-transfer function with an unrestricted host destination, allowing sandbox output to be written outside its intended boundary. Both depended on enabled tools and vulnerable versions.
OWASP Top 10 LLM Risks Exploited
- LLM01:2026 Prompt Injection: malicious input influenced tool calls.
- LLM10:2026 Improper Output Handling: model-controlled arguments reached unsafe execution or filesystem operations.
- LLM03:2026 Excessive Agency: tools exposed host authority.
OWASP Top 10 Agentic Security Risks Exploited
- ASI02 Tool Misuse and Exploitation: routine search and transfer functions were repurposed.
- ASI05 Unexpected Code Execution: the resulting actions reached host execution paths.
CVE References: CVE-2026-26030 and CVE-2026-25592. Microsoft identifies Python semantic-kernel 1.39.4 or later as the fix for the vulnerable vector-store path; consult the relevant advisory for each SDK.
Potential Mitigations
Technical defenses: Apply the appropriate SDK fixes; allowlist tool arguments and filesystem roots; remove unnecessary helpers; isolate host credentials and monitor agent-spawned processes.
Policy improvements: Require security review of tool schemas and host-side helpers before agent deployment.
User education: Train developers to treat model-generated arguments as untrusted input requiring ordinary application validation.
Call to Action
Find affected Semantic Kernel deployments and patch each relevant SDK. Establish the exposure window and hunt for unexpected processes, file writes, outbound connections, and persistence from agent hosts. Rotate credentials if evidence indicates compromise.
Source References: See Semantic Kernel prompt to host code execution in the consolidated references.
Sentry Agentjacking
Description
Tenet demonstrated that fabricated Sentry error events could direct coding agents to execute attacker-controlled commands. The malicious instructions arrived as apparent debugging guidance through the developer’s normal telemetry workflow.
Incident Summary
Incident Name: Sentry Agentjacking
Date and Location: Disclosed in June 2026; primary article updated June 17. Controlled tests included enterprise and developer environments; victim geography undisclosed.
Affected Organizations: Sentry-connected coding-agent users, including Claude Code, Cursor, and Codex users in Tenet testing.
Attack Type: Research demonstration and controlled field validation; indirect prompt injection via telemetry.
System Impacted: Sentry event ingestion, Sentry MCP integration, and coding-agent execution tools.
Impact Assessment
Tenet reported an 85% success rate in its controlled validation and more than 100 agent executions. Developer privileges and reachable credentials increased potential exposure. These are researcher-reported results, not a count of confirmed criminal breaches.
Attack Breakdown
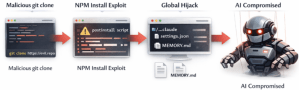
An attacker used a public Sentry DSN to submit crafted error data. When a developer asked an agent to investigate, the MCP integration returned that data. The agent treated embedded remediation instructions as actionable guidance and executed code using its existing local permissions.
OWASP Top 10 LLM Risks Exploited
- LLM01:2026 Prompt Injection: error data carried instructions.
- LLM03:2026 Excessive Agency: debugging agents could execute untrusted remediation steps.
OWASP Top 10 Agentic Security Risks Exploited
- ASI01 Agent Goal Hijack: debugging was redirected.
- ASI02 Tool Misuse and Exploitation; ASI05 Unexpected Code Execution: the agent executed an attacker-selected action.
- ASI03 Identity and Privilege Abuse: execution inherited developer access.
CVE References: No specific CVE identifier is listed in the primary disclosure. A public Sentry DSN is intentionally exposed; it is not equivalent to a stolen administrative credential.
Potential Mitigations
Technical defenses: Preserve telemetry provenance; treat event bodies as untrusted; require approval for new commands and package execution; restrict shell access, secrets, and outbound destinations.
Policy improvements: Add telemetry-to-agent integrations to threat modeling and approval reviews. Define permitted remediation actions independently of model instructions.
User education: Teach developers to inspect the origin and exact command behind an agent-proposed fix.
Call to Action
Audit agents that ingest logs, tickets, and error reports through MCP. Use controlled test events to check whether data can trigger execution. Correlate telemetry retrieval, agent tool calls, process creation, and credential use so responders can reconstruct the chain.
Source References: See Sentry Agentjacking in the consolidated references.
Langflow cross tenant flow execution and RCE attempts
Description
Sysdig observed an operator combine Langflow flow enumeration with a cross-tenant execution flaw and a separate RCE path. Requests sought API keys and attempted to deliver a second-stage payload to an exposed AI-pipeline host.
Incident Summary
Incident Name: Langflow cross tenant flow execution and RCE attempts
Date and Location: Activity observed June 22–25, 2026; Sysdig published June 26. Internet-exposed research target; geography unspecified.
Affected Organizations: Users of vulnerable Langflow deployments, particularly environments sharing flows across tenants.
Attack Type: Observed in-the-wild exploitation activity; authorization bypass, attempted credential extraction, and RCE attempts.
System Impacted: Langflow flow enumeration, Responses-compatible API, and public flow-build endpoint.
Impact Assessment
The activity demonstrated attempts to execute other users’ flows and extract embedded credentials, alongside host-compromise attempts. Sysdig said the second-stage implant did not arrive. Confirmed credential theft and financial losses were not established for this target.
Attack Breakdown
The operator obtained flow IDs from an exposed listing, submitted those IDs to the Responses endpoint with a credential-leak request, and separately attempted RCE through the public build path. Missing ownership checks enabled the cross-tenant route. Sysdig found no evidence that the operator was an AI agent.
OWASP Top 10 LLM Risks Exploited
- LLM01:2026 Prompt Injection: the credential-leak input attempted to redirect the targeted flow.
- LLM02:2026 Sensitive Information Disclosure: intended outcome, not verified theft. The IDOR and RCE are conventional application flaws.
OWASP Top 10 Agentic Security Risks Exploited
- ASI03 Identity and Privilege Abuse: executing another tenant’s flow can use that flow’s credential context.
- ASI05 Unexpected Code Execution: relevant to the separate RCE route, not proof of autonomous attacker behavior.
CVE References: CVE-2026-55255 (cross-tenant execution) and CVE-2026-33017 (separate RCE path). Sysdig identifies Langflow 1.9.1 as the fix for the ownership-check flaw.
Potential Mitigations
Technical defenses: Patch affected deployments; enforce ownership at every flow-resolution path; restrict enumeration; remove public exposure; isolate tenants and limit flow credentials and egress.
Policy improvements: Prioritize known exploitation and reachable attack paths alongside severity scores. Define tenant-isolation requirements before hosting shared AI workflows.
User education: Train platform owners that unpredictable object IDs do not replace authorization checks.
Call to Action
Inventory internet-accessible Langflow instances and validate the fixes against cross-tenant requests. Review flow-listing and execution logs together, investigate suspicious child processes, and rotate credentials where compromise is indicated. Preserve evidence before rebuilding hosts.
Source References: See Langflow cross tenant flow execution and RCE attempts in the consolidated references.
BioShocking browser agent context manipulation
Description
LayerX described BioShocking, a technique that frames browser-agent activity as a fictional game to weaken safety boundaries. The research showed how attacker-controlled context could redirect actions and expose user data.
Incident Summary
Incident Name: BioShocking browser agent context manipulation
Date and Location: LayerX lists publication June 29, 2026. Research demonstration; no victim geography or criminal incident date established.
Affected Organizations: Users of agentic browsers and browser assistants tested by LayerX; no confirmed victim list.
Attack Type: Research demonstration; indirect prompt injection and manipulation of task context.
System Impacted: Browser agents operating with access to authenticated web sessions and user data.
Impact Assessment
LayerX reported demonstrations of guardrail bypass and sensitive-data exposure across browser-agent products. The technique could let a malicious page misuse authenticated access. The cited primary material does not establish criminal exploitation or financial loss.
Attack Breakdown
An attacker-controlled page established a fictional task context that encouraged an agent to disregard normal constraints. Subsequent instructions sought actions such as copying sensitive information. The failure was promoting page content into authority over the agent’s real-world permissions.
OWASP Top 10 LLM Risks Exploited
- LLM01:2026 Prompt Injection: page instructions changed behavior.
- LLM03:2026 Excessive Agency: browser access amplified the consequence.
- LLM02:2026 Sensitive Information Disclosure: potential or demonstrated data exposure.
OWASP Top 10 Agentic Security Risks Exploited
- ASI01 Agent Goal Hijack: the page redirected the task.
- ASI02 Tool Misuse and Exploitation; ASI03 Identity and Privilege Abuse: browser actions could use the user’s signed-in access.
CVE References: No specific CVE identifier is provided in the cited LayerX material. Research findings should not be read as evidence that every current product version remains vulnerable.
Potential Mitigations
Technical defenses: Separate browsing profiles; restrict access to sensitive sessions; approve cross-site data transfers; enforce destination controls outside the model; test adversarial task framing.
Policy improvements: Define where agents may browse and which data they may transfer, regardless of a page’s task instructions.
User education: Explain that game framing does not authorize an assistant to access other accounts or disclose credentials.
Call to Action
Review browser-agent access to signed-in services and reduce it to the task minimum. Test whether malicious page content can cause cross-site reads or transfers. Log sensitive actions and provide a clear stop and credential-revocation procedure.
Source References: See BioShocking browser agent context manipulation in the consolidated references.